
Today: loose ends: no-copy, is, better/shorter code, flex-arrow example
Below are some other Python list functions. If a CS106A problem required one of these, the problem statement would mention it specifically. We're just mentioning them for completeness, so you will have a slight memory that these exist.
Here are some "list2" practice problems on the server if you are curious, but you do not need to do these.
> list2 exercises
lst.extend(lst2)(We didn't do this one in L18)
To add a single element to a list, we use lst.append(elt). The similar lst.extend(lst2) does not add a single element. Instead, its parameter is a second list, and it appends all the elements from the second list.
`lst.extend(lst2)` - add all the elements of lst2 on to the end of lst.
lst = [1, 2, 3]
x =[4, 5]
# what happens .append vs. extend
# extend:
lst.extend(x) -> all elements of x are added at end,
  so lst is [1, 2, 3, 4, 5]

# append:
lst.append(x) -> x is added as an *element*,
  so lst is [1, 2, 3, [4, 5]]
Alternately + can be used similarly to its action with strings: lst + lst2 puts all their elements together to make a new, big list, e.g. [1, 2] + [3, 4] -> [1, 2, 3, 4], leaving the original lists as they were.
lst.pop(), lst.pop(index)lst.pop() - remove the element from the end of the list and return it, decreasing the length of the list by 1, i.e. the opposite of append(). Elements shift down to keep the list contiguous.
lst.pop(index) - alternate version with the index to remove is given, e.g. lst.pop(0) removes the first element from the list.
>>> lst = ['a', 'b', 'c', 'd']
>>> lst.pop()   # default = remove from end
'd'
>>> lst
['a', 'b', 'c']
>>> lst.pop(0)  # can specify index to pop
'a'
>>> lst
['b', 'c']
lst.insert(index, elem)>>> lst = ['a', 'b'] >>> lst.insert(0, 'z') >>> lst ['z', 'a', 'b']
lst.remove(target)
>>> lst = ['a', 'b', 'c', 'b']
>>> lst.remove('b')
>>> lst
['a', 'c', 'b']
When your Python assigns a variable with =, say with a list or string value, Python does not copy the underlying list or string. Instead, it sets that variable with an additional pointer to the original list or string. There is one list with two pointers to it.
>>> a = [1, 2, 3, 4]
>>> b = a   # b points to the same as a
>>> a
[1, 2, 3, 4]
>>> b
[1, 2, 3, 4]
We can see that the value is shared by the two pointers, since making a change to a, we see that change reflected in b — the two variables are pointing to the same thing.
>>> a.append(99)
>>> a
[1, 2, 3, 4, 99]
>>> b
[1, 2, 3, 4, 99]
>>>

Programming in Python, your mental model should be that you have a structure like a list, and when you use = on it or pass that structure as a parameter to a function, the list is not copied. Instead, the variable or called function gets an additional pointer to the one underlying list. This is the picture to have in mind building a Python program — one object in memory you are working on, and pointers to that one object proliferating around in the code. (Some other computer languages makes copies of lists and strings in some circumstances. Python is relatively simple, as it just never makes a copy.)
We're just mentioning this for copleteness, as we are never going to use this feature in CS106A. Sometimes, you have a list, and you really do want a copy, so that if you change the copy, the original list is unchanged. There is a .copy() function that works on many Python structures, including lists. It makes a duplicate structure, and populates it the same elements from the original structure.
>>> c = a.copy()  # copy() - new list, populated with a elements
>>> c = a[:]      # same as above - slice copy of whole list

>>> a[0] = -1     # change to a, not seen in c
>>>
>>> a
[-1, 2, 3, 4, 99]
>>> c
[1, 2, 3, 4, 99
>>>
is ComparisonThe is comparison operator does not compute something most programs need IMHO, and you should rarely need it.
The is comparison computes if two values occupy the same bytes in memory. In contrast, the more useful == operator simply checks if two values look the same. As a practical matter, it is extremely rare for an algorithm to need the is operator.
>>> a = [1, 2, 3, 4, 99]
>>> b = a
>>> c = a.copy()
>>>
>>> a is b          # "is" True - they are same memmory
True
>>>
>>> a == c          # == True - values look the same
True
>>>
>>> a is c          # "is" False - not same memory
False
>>>
is None1. Say we have a word variable. The following if-statement will work perfectly for CS106A, and you probably wrote it that way before, and it's fine and we will never mark off for it.
if word == None:       # Works perfectly, not PEP8
    print('Nada')
2. Unfortunately, there is a very old rule in PEP8 that comparisons to the value None should be written with the is operator. This is an awkward rule, but we are stuck with it. You may have noticed PyCharm complaining about the above form, so you can write it as follows and it works correctly and is PEP8:
if word is None:       # Works perfectly, PEP8
    print('Nada')


if word is not None:   # "is not" variant
    print('Not Nada')
Very important limitation:
3. The is operator works reliably with the value None. Used with regular strings and lists, the is operator will typically not do what you need or expect. Therefore, the rule is:
Never use the is operator for values other than None.
Never, never, never, never.
Only use is with None as above. If you use it with other values, it will lead to horrific, weekend-ruining bugs.
There's a longer explanation about this awkward "is" rule in the guide page above.
We'll look at a more powerful technique, nesting one structure inside of another.
Suppose each day we track the low and high temperature for that day and a list length-2. Here we have the temperatures for Mon and Tue:
>>> mon = [49, 66]
>>> tue = [50, 67]
>>>
>>> temps = []
>>>
For copy/paste: mon = [49, 66]; tue = [50, 67] ; temps = []
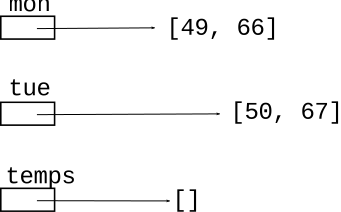
mon and tue inside temps?It is deceptively simple - use append(), just the regular way, specifying mon as the element to add to the list.
>>> temps.append(mon)
>>> temps.append(tue)
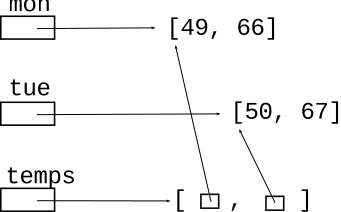
Following the no-copy rule, this does not copy the list, but stores and additional pointer to mon as an element inside the list.
66What are two expressions to retrieve 66, the number inside of mon
>>> # 1. Using mon variable
>>> mon[1]
66
>>> # 2. Using temps variable
>>> temps[0][1]
66
>>>
temps[0][1]In temps[0][1], look at the square bracket pairs from left to right. These work into the data structure from the outside.
>>> temps
[[49, 66], [48, 67]]
>>> temps[0]
[49, 66]
>>> temps[0][1]
66
temps[0] and mon>>> mon [49, 66] >>> temps[0] [49, 66] >>>
50 to 48 via temps>>> temps[1] [50, 67] >>> temps[1][0] 50 >>> temps[1][0] = 48 >>> temps[1] [48, 67] >>>
Not showing any new python, but showing moves and patterns you may not have thought of to shorten and clean up your code.
Many of these techniques involve leveraging variables to clean up the code.
Say we want to set alarm differently for weekends, something like this:
if is_weekened:
    alarm = 'off'
else:
    alarm = '9:00 am'
The above code is fine. Here I will propose a slightly shorter way, and this is used below. (1) Initialize (set) the variable to its common, default value first. (2) Then an if-statement detects the case where the var should e set to a different value.
alarm = '9:00 am'
if is_weekend:
    alarm = 'off'
if case-1:
    lines-a
    ...
    ...

if case-2:
    lines-b
    ...
    ...
grounded(minutes, is_birthday): Given you came home minutes late, how many days of grounded are you. If minutes is an hour or less, grounding is 5, otherwise 10. Unless it is your birthday, then 30 extra minutes are allowed. Challenge: change this code to be shorter, not have so much duplicated code.
The code below works correctly. You can see there is one set of lines for the birthday case, and another set of similar lines for the not-birthday case. What exactly is the difference between these two sets of lines?
def grounded(minutes, is_birthday):
    if not is_birthday:
        if minutes <= 60:
            return 5
        return 10

    # is birthday
    if minutes <= 90:
        return 5
    return 10
1. Set limit first. 2. Then unified lines below use limit, work for all cases.
def grounded(minutes, is_birthday):
    limit = 60
    if is_birthday:
        limit = 90

    if minutes <= limit:
        return 5
    return 10
ncopies: word='bleh' n=4 suffix='@@' ->

   'bleh@@bleh@@bleh@@bleh@@'


ncopies: word='bleh' n=4 suffix='' ->

   'bleh!bleh!bleh!bleh!'
ncopies(word, n, suffix): Given name string, int n, suffix string, return
n copies of string + suffix.
If suffix is the empty string, use '!' as the suffix.
Challenge: change this code to be shorter,
not have so many distinct paths.
The problem starts with eversion below as a starting point. Look at lines that are similar - make a unified version of those lines using a variable, as above.
Before:
def ncopies(word, n, suffix):
    result = ''

    if suffix == '':
        for i in range(n):
            result += word + '!'
    else:
        for i in range(n):
            result += word + suffix
    return result
Solution: use logic to set an ending variable to hold what goes on the end for all cases. Later, unified code uses that variable vs. separate if-stmt for each case. Alternately, could use the suffix parameter as the variable, changing it to '!' if it's the empty string.
def ncopies(word, n, suffix):
    result = ''
    ending = suffix
    if ending == '':
        ending = '!'

    for i in range(n):
        result += word + ending
    return result
> match()
match(a, b): Given two strings a and b. Compare the chars of the strings at index 0, index 1 and so on. Return a string of all the chars where the strings have the same char at the same position. So for 'abcd' and 'adddd' return 'ad'. The strings may be of any length. Use a for/i/range loop. The starter code works correctly. Re-write the code to be shorter.
match():
 'abcd'
 'adddd'  -> 'ad'
  01234
Code before unify:
def match(a, b):
    result = ''
    if len(a) < len(b):
        for i in range(len(a)):
            if a[i] == b[i]:
                result += a[i]
    else:
        for i in range(len(b)):
            if a[i] == b[i]:
                result += a[i]
    return result
def match(a, b):
    result = ''
    # Set length to whichever is shorter
    length = len(a)
    if len(b) < len(a):
        length = len(b)

    for i in range(length):
        if a[i] == b[i]:
            result += a[i]

    return result
If we have time, a fun bit of drawing code.
Download the flex-arrow.zip to work this fun little drawing example.
Recall: floating point values passed into draw_line() etc. work fine.
Ultimately we want to produce this output:
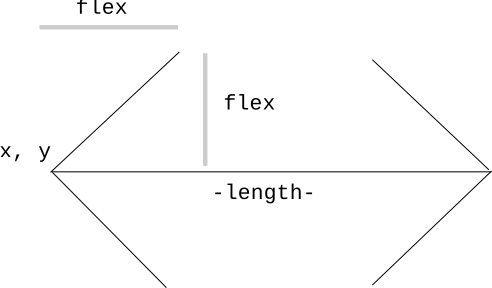
flex_factor = 0.2
flex = flex_factor * length
The flex_factor parameter is 0..1.0: the fraction of the arrow's length used for the arrow heads. The arms of the arrow will go at a 45-degree angle away from the horizontal.
Specify flex on the command line so you can see how it works, here calling the version with the code completed. Close the window to exit the program. The main() draws 2 arrows, one above the other. You can also specify larger canvas sizes.
$ python3 flex-arrow-solution.py -arrows 0.25
$ python3 flex-arrow-solution.py -arrows 0.15
$ python3 flex-arrow-solution.py -arrows 0.1 1200 600
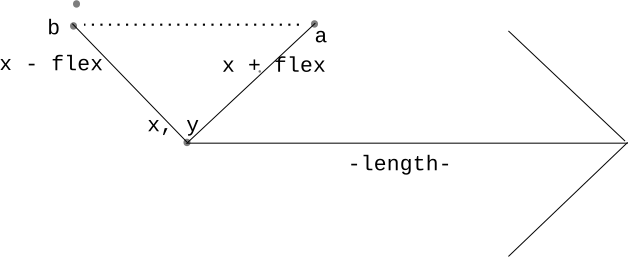
Look at the draw_arrow() function. It is given x,y of the left endpoint of the arrow and the horizontal length of the arrow in pixels. The flex_factor is in 0..1.0, giving the percent of length to add/subtract to make the arrow heads.
This starter code has the first half of the drawing done.
def draw_arrow(canvas, x, y, length, flex_factor):
    """
    Draw a horizontal line with arrow heads at both ends.
    Its left endpoint at x,y, extending for length pixels.
    flex_factor is 0.0 .. 1.0, the fraction of length
    to add/subtract from ends to make the arrow heads.
    """
    # Compute where the line ends, draw it
    x_right = x + length - 1
    canvas.draw_line(x, y, x_right, y)

    # Draw 2 arrowhead lines, up and down from left endpoint
    flex = flex_factor * length
    # what goes here?
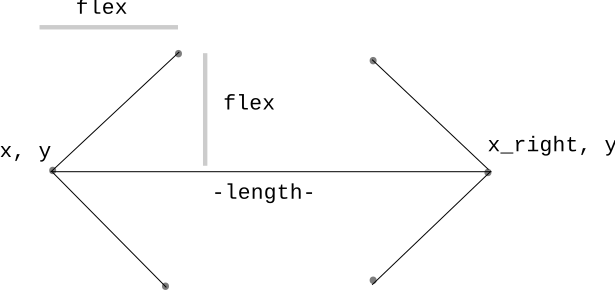
With flex computed - what the two lines to draw the left arrow head? This is a nice visual algorithmic problem.
Code to draw left arrow head. Note the arrowhead lines are not "flex" pixels long. Flex is just the number we add and subtract, derived from flex_factor.
    flex = flex_factor * length
    canvas.draw_line(x, y, x + flex, y - flex)  # up
    canvas.draw_line(x, y, x + flex, y + flex)  # down
Add code draw_arrow() in flex-arrow.py to draw the head on the right endpoint of the arrow. This is a little CS106A applied-math exercise. In the function, the variable x_right is the x coordinate of the right endpoint of the line:x_right = x + length - 1
Add "up" and "down" diagonal lines to form the right arrowhead.
When that code is working, this should draw both arrows (or use the flex-arrow-solution.py):
$ python3 flex-arrow.py -arrows 0.1 1200 600
def draw_arrow(canvas, x, y, length, flex_factor):
    """
    Draw a horizontal line with arrow heads at both ends.
    Its left endpoint at x,y, extending for length pixels.
    flex_factor is 0.0 .. 1.0, the fraction of length
    to add/subtract from ends to make the arrow heads.
    """
    # Compute right x endpoint, draw horizontal line
    x_right = x + length - 1
    canvas.draw_line(x, y, x_right, y)

    # Draw left arrowhead, add/subtract flex from x,y
    flex = flex_factor * length
    canvas.draw_line(x, y, x + flex, y - flex)  # up
    canvas.draw_line(x, y, x + flex, y + flex)  # down

    # Draw right arrowhead from the right endpoint
    # your code here
    pass
    canvas.draw_line(x_right, y, x_right - flex, y - flex)  # up
    canvas.draw_line(x_right, y, x_right - flex, y + flex)  # down
Now we're going to show you something a little beyond the regular CS106A level, and it's a teeny bit mind warping.
Run the code with -trick like this, see what you get.
$ python3 flex-arrow-solution.py -trick 0.1 1000 600