Hotelling’s two sample test
Two-sample tests

\[F_1 \overset{?}{=} F_2\]
Olive oil data
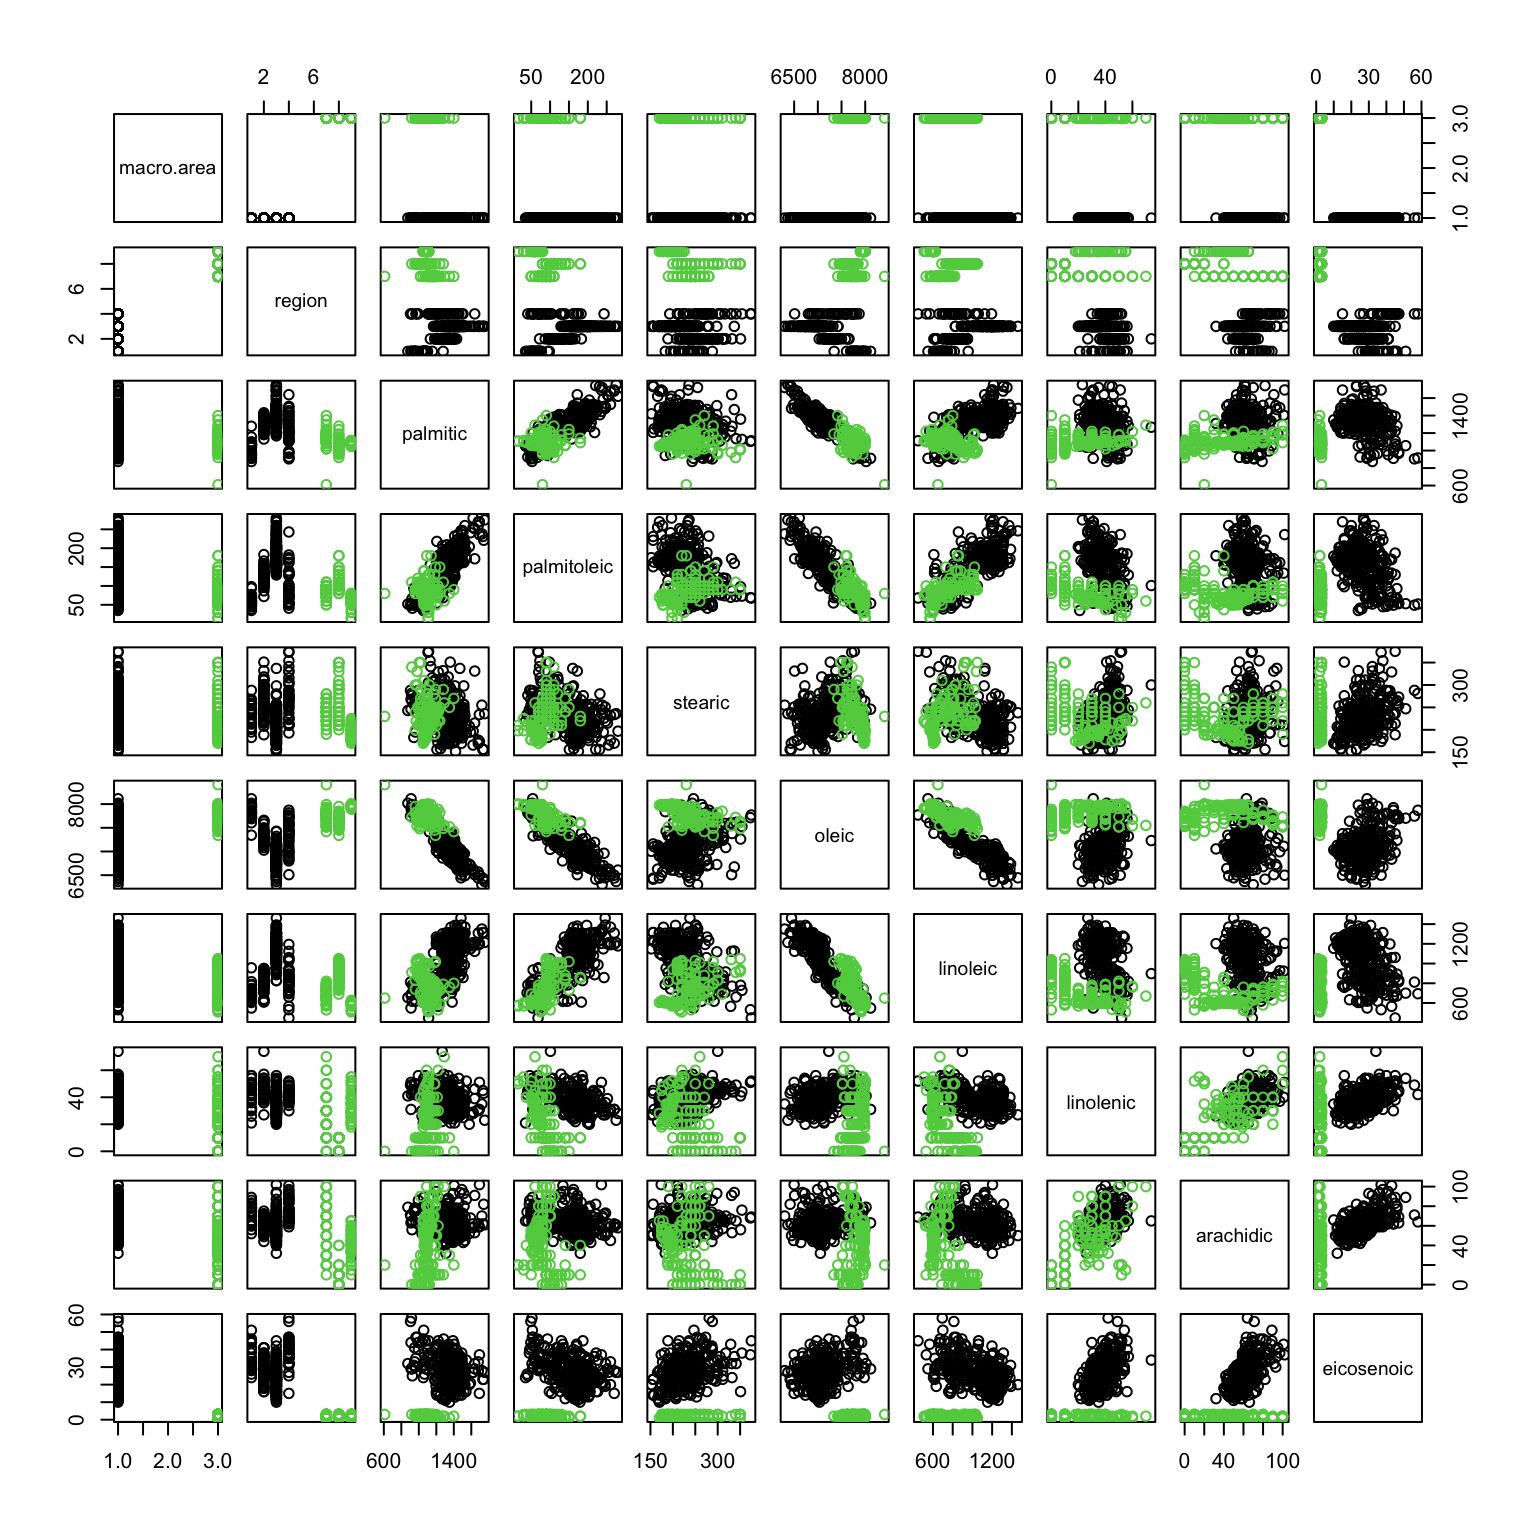
North vs. south
Two-sample tests: model
Consider \(X_1 \in \mathbb{R}^{n_1 \times p}\) an \(N(\mu_1, \Sigma_1)\) data matrix and \(X_2 \in \mathbb{R}^{n_2 \times p}\) and \(N(\mu_2, \Sigma_2)\) data matrix.
Assuming \(\Sigma_1=\Sigma_2\) we consider testing \(H_0: \mu_1=\mu_2\).
Hotelling’s \(T^2\) test
- Obvious (?) candidate
\[ T^2_p = (\bar{X}_1 - \bar{X}_2)^T \left(S_p \left(\frac{1}{n_1} + \frac{1}{n_2} \right)\right)^{-1} (\bar{X}_1 - \bar{X}_2). \]
with
\[ \begin{aligned} S_p &= \frac{1}{n_1+n_2-2} \left(X_1^T(I_{n_1} - H_1)X_1 + X_2^T(I_{n_2} - H_2) X_2 \right) \\ & \sim \textrm{Wishart}\left(\frac{\Sigma}{n_1+n_2-2}, n_1+n_2-2 \right) \\ H_1 &= \frac{1}{n_1} 1_{n_1}1_{n_1}^T \\ H_2 &= \frac{1}{n_2} 1_{n_2} 1_{n_2}^T \end{aligned} \]
- Under \(H_0: T^2 \sim \frac{mp}{m-p+1} F_{p,m-p+1}\)
Computing the test statistic
n_1 = nrow(X_1)
n_2 = nrow(X_2)
p = ncol(X_1)
S_p = (((n_1 - 1) * cov(X_1) + (n_2 - 1) * cov(X_2))
       / (n_1 + n_2 - 2))
diff = apply(X_1, 2, mean) - apply(X_2, 2, mean)
T2 = n_1 * n_2 / (n_1 + n_2) * t(diff) %*% solve(S_p) %*% diff
m = n_1 + n_2 - 2
F = (m - p + 1) / (p * m) * T2
pvalue = 1 - pf(F, p, m - p + 1)
data.frame(F=F, T2=T2, num=p, denom=m-p+1, pvalue)
F T2 num denom pvalue
1 405.3333 3291.481 8 465 0Using a package
A harder test
Distribution of test statistic
- Easy to see under \(H_0\)
\[ T^2_p = Z^T\left(\frac{1}{n_1+n_2-2} W\right)^{-1} Z \overset{D}{=} \textrm{Hotelling}(n_1+n_2-2,p) \]
with
\[ \begin{aligned} Z &= \left(\frac{\Sigma}{\frac{1}{n_1}+\frac{1}{n_2}}\right)^{-1/2} \left(\bar{X}_1 - \bar{X}_2\right) \sim N(0, I) \\ W &= \Sigma^{-1/2}S_p\Sigma^{-1/2} \sim \frac{1}{n_1+n_2-2}\textrm{Wishart}(I, n_1+n_2-2) \end{aligned} \]
Largest \(t\) statistic interpretation
- Let
\[ t^2(a) = t^2(a;X_1,X_2,S_p) = \frac{1}{\frac{1}{n_1} + \frac{1}{n_2}} \frac{\left(a^T(\bar{X}_1-\bar{X}_2)\right)^2}{a^TS_pa} \sim \textrm{Student}(n_1+n_2-2)^2 \]
- Then,
\[ T^2_p = \sup_{a \in \mathbb{R}^p} t^2(a). \]
- Quick check
\[ \begin{aligned} \sup_{a \in \mathbb{R}^p} t^2(a) &= \sup_{b \in \mathbb{R}^p} t^2(S_p^{-1/2}b) \\ &= \frac{1}{\frac{1}{n_1} + \frac{1}{n_2}} \sup_{b \in \mathbb{R}^p} \frac{\left(b^TS_p^{-1/2}(\bar{X}_1-\bar{X}_2)\right)^2}{b^Tb} \\ &= \frac{1}{\frac{1}{n_1} + \frac{1}{n_2}} \|S_p^{-1/2}(\bar{X}_1-\bar{X}_2)\|^2_2 \end{aligned} \]
- Alternatively,
\[ T^2_p = \left(\sup_{a: a^TS_p a \leq 1} a^T\left(\frac{\bar{X}_1-\bar{X}_2}{\sqrt{ \frac{1}{n_1}+\frac{1}{n_2}}}\right) \right)^2 \]
Asymptotic behavior
- As \(n_1, n_2 \to \infty\) and \(S_p \to \Sigma\) (recall we assume \(\textrm{Var}(X_1)=\textrm{Var}(X_2))\). Plugging in…
\[ \begin{aligned} T^2_p &\to \left(\sup_{a: a^T\Sigma a\leq 1} a^T\left(\frac{\bar{X}_1-\bar{X}_2}{\sqrt{ \frac{1}{n_1}+\frac{1}{n_2}}}\right) \right)^2 \\ &= \frac{1}{\frac{1}{n_1}+\frac{1}{n_2}} (\bar{X}_1-\bar{X}_2)^T\Sigma^{-1}(\bar{X}_1-\bar{X}_2) \\ & \overset{H_0}{\sim} \chi^2_p \end{aligned} \]
under \(H_0: E(X_1)=E(X_2)\) (and equal variances).
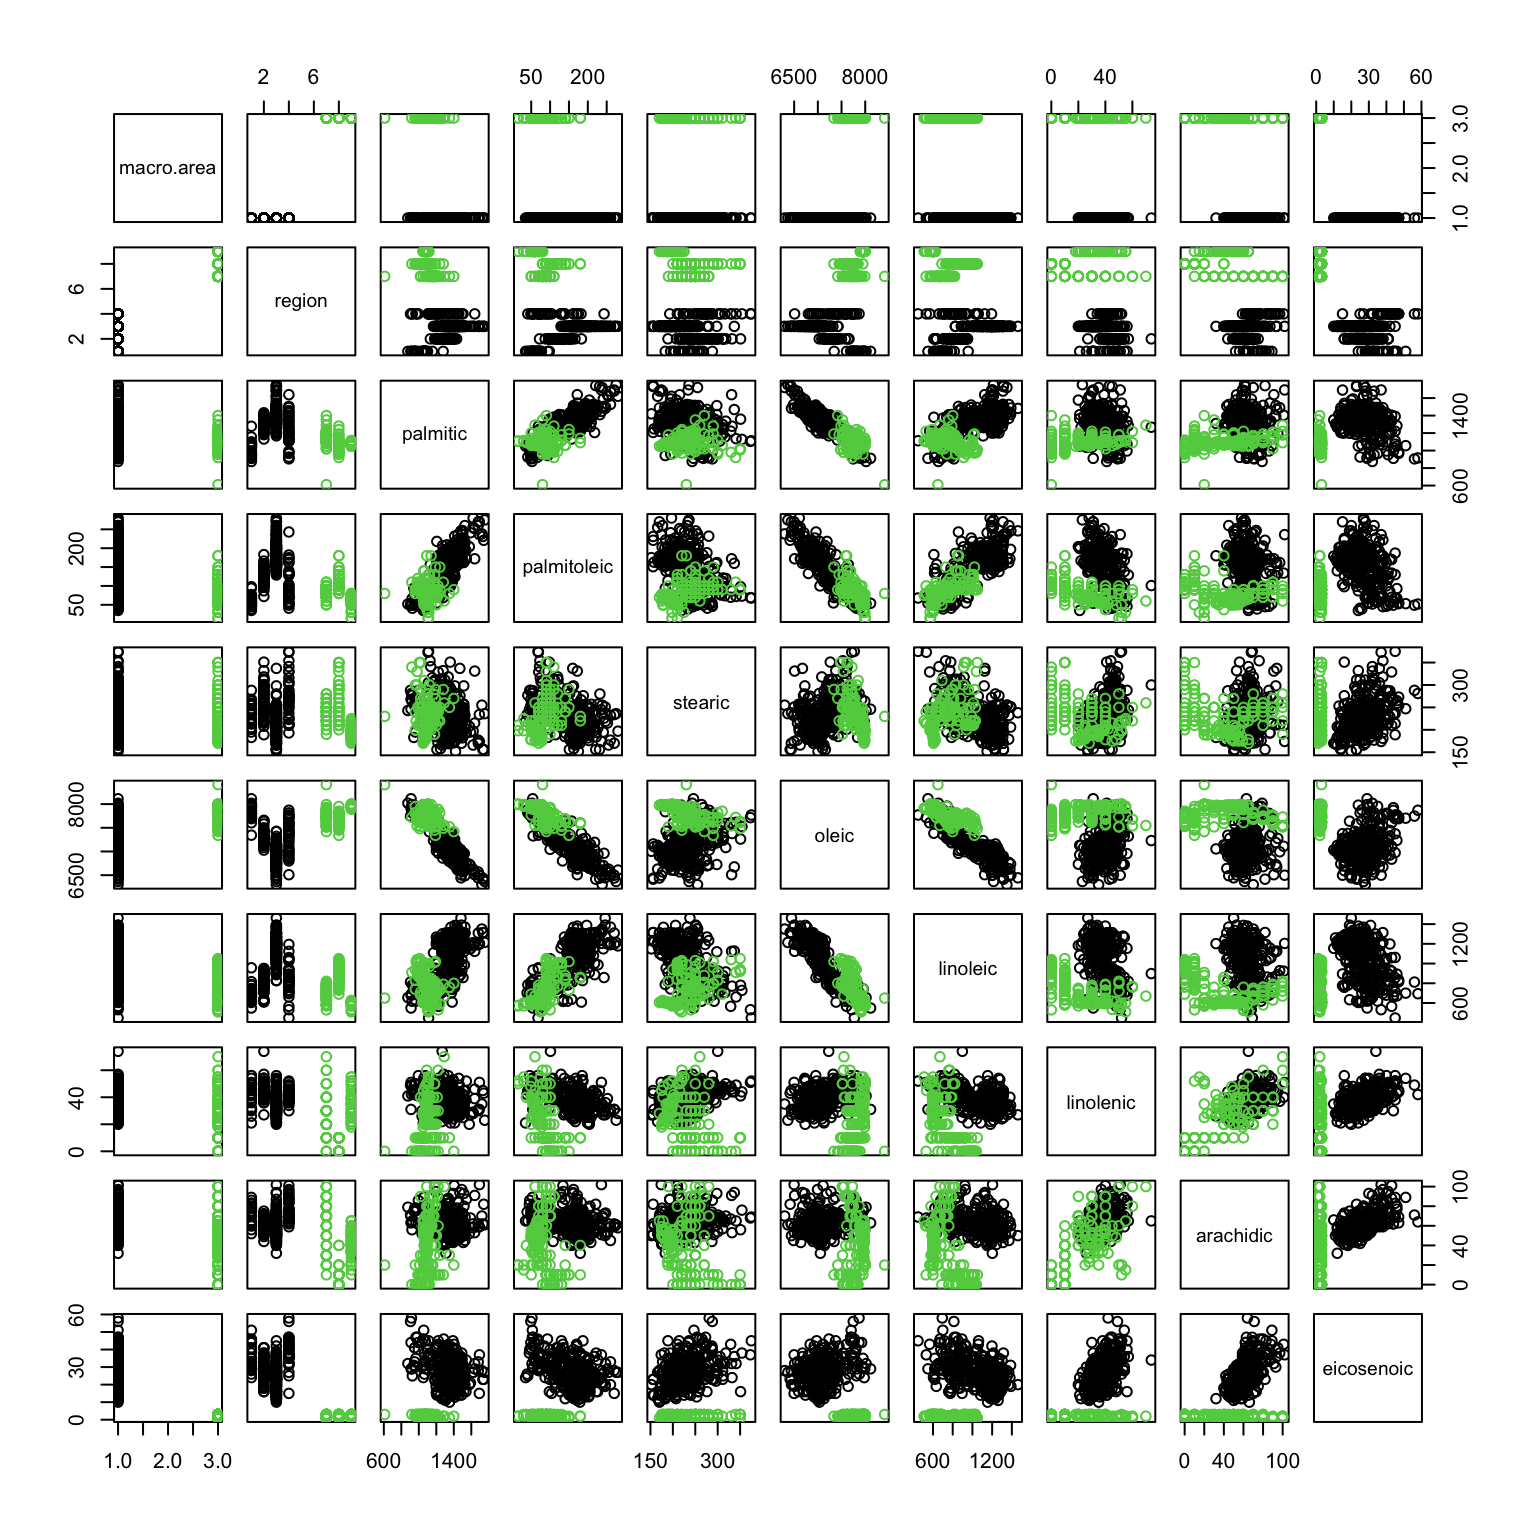
Equal variances?
Calibration using permutation
Test stat:  405.33
Numerator df:  8
Denominator df:  465
Permutation P-value:  0
Number of permutations : 10000
Harder version
Alternative tests
- Instead of maximizing over \(\{a: a^T\Sigma a \leq 1\}\) might consider analog of Bonferroni (over coordinate directions \(e_j\))
\[ \sup_{a \in \left\{ \pm e_j/\sqrt{\Sigma_{jj}}, 1 \leq j \leq p\right\}} a^T\left(\frac{\bar{X}_1-\bar{X}_2}{\sqrt{ \frac{1}{n_1}+\frac{1}{n_2}}}\right) \]
- Or,
\[ \sup_{a : a^Ta \leq 1} a^T\left(\frac{\bar{X}_1-\bar{X}_2}{\sqrt{ \frac{1}{n_1}+\frac{1}{n_2}}}\right) = \left\|\frac{\bar{X}_1-\bar{X}_2}{\sqrt{ \frac{1}{n_1}+\frac{1}{n_2}}}\right\|_2 \overset{D}{=} \left(\sum_{i=1}^p \lambda_i(\Sigma) Z_i^2\right)^{1/2} \]
with \(Z \sim N(0, I_{p \times p})\).
Calibrating tests: Roy’s union-intersection principle (5.2.2 of MKB)
For simplicity let’s take \(n_1, n_2 \gg 1\) and \(\Sigma=I\)
Null hypothesis is an intersection
\[ H_0 = \cap_{a \in A} H_{0,a} \]
with
\[ H_{0,a} = \left\{(\mu_1,\mu_2): a^T(\mu_1-\mu_2)=0 \right\}. \]
- Suppose that for each \(a \in A\) we have a test statistic to test \(H_{0,a}\) (under \(n_1, n_2 \gg 1\))
\[ Z(a) = Z(a;X_1,X_2) = a^T\left(\frac{\bar{X}_1-\bar{X}_2}{\sqrt{ \frac{1}{n_1}+\frac{1}{n_2}}}\right) \overset{H_{0,a}}{\sim} N(0,1). \]
- Consider rejection regions that are unions
\[ R = \cup_{a \in A} \left\{(X_1,X_2): Z(a;X_1,X_2) \geq z_a \right\} \]
- Most common to pick \(z_{\alpha}\) chosen so that under \(H_0\)
\[ P\left(\sup_{a \in A}Z(a) \geq z_{\alpha} \right) \approx \alpha \]
Back to Hotelling’s \(T^2\)
Returning to finite samples, Hotelling’s \(T^2\) test uses \(t^2(a; X_1, X_2)\) with pooled estimate of covariance for each direction \(a\). Cutoff chosen from relation to \(F\) distribution…
For two alternative tests presented, calibration must be done by bounding (i.e. Bonferroni bound), simulation (including permutation) or more careful analysis.
Another look at Hotelling \(T^2\)
- Let’s stack the data to form
\[ X = \begin{pmatrix} X_1 \\ X_2 \end{pmatrix} \]
Rewriting the statistic
Let \[ M_1 = \frac{1}{n_1} \begin{pmatrix} 1_{n_1} \\ 0_{n_2} \end{pmatrix}, \qquad M_2 = \frac{1}{n_2} \begin{pmatrix} 0_{n_1} \\ 1_{n_2} \end{pmatrix}. \]
Difference of means is
\[ \bar{X}_1 - \bar{X_2} = X^T(M_1 - M_2) \]
\(T^2\) as a trace
\[ \begin{aligned} T^2 &= \frac{1}{\frac{1}{n_1}+\frac{1}{n_2}}(\bar{X}_1-\bar{X}_2)^TS_p^{-1}(\bar{X}_1-\bar{X}_2) \\ &= \frac{1}{\frac{1}{n_1}+\frac{1}{n_2}} \textrm{Tr}(S_p^{-1}X^T(M_1-M_2)(M_1-M_2)^TX) \\ &= \textrm{Tr}(XS_p^{-1}X^TP^{\Delta}) \\ \end{aligned} \]
Differencing projection
\[ P^{\Delta} = \frac{1}{\frac{1}{n_1}+\frac{1}{n_2}} (M_1-M_2)(M_1-M_2)^T \]
Numerical check
X = as.matrix(rbind(X_1, X_2))
n_1 = nrow(X_1)
n_2 = nrow(X_2)
M_1 = c(rep(1, n_1), rep(0, n_2)) / n_1
M_2 = c(rep(0, n_1), rep(1, n_2)) / n_2
P_delta = (M_1 - M_2) %*% t(M_1 - M_2) * n_1 * n_2 / (n_1 + n_2)
S_p = ((n_1 - 1) * cov(X_1) + (n_2 - 1) * cov(X_2)) / (n_1 + n_2 - 2)
T2_alt = sum(diag(X %*% solve(S_p) %*% t(X) %*% P_delta))
c(T2, T2_alt)
[1] 3291.481 3291.481Form of the test statistic
Take any symmetric \(G\) \[ G = \begin{pmatrix} G_{11} & G_{12} \\ G_{21} & G_{22} \end{pmatrix} \]
The statistic takes the form \[ \begin{aligned} \text{Tr}(GP^{\Delta}) &= \frac{1}{n_1^2} \sum_{i,j=1}^{n_1} G_{11}[i,j] \\ & \qquad - \frac{2}{n_1n_2} \sum_{i=1}^{n_1} \sum_{j=1}^{n_2} G_{12}[i,j] \\ & \qquad + \frac{1}{n_2^2} \sum_{i,j=1}^{n_2} G_{22}[i,j] \\ \end{aligned} \]
Can be interpreted as (average) within-group similarity minus (average) between-group similarity…
May want to remove diagonal entries (more shortly)
- Imagining \(n_1, n_2 \to \infty\) this becomes approximately
\[ \begin{aligned} \textrm{Tr}(P^{\Delta}X\Sigma^{-1}X^TP^{\Delta}) &= \textrm{Tr}(P^{\Delta}GP^{\Delta}) \\ \end{aligned} \]
where \(G_{n \times n}\) is a Gram matrix (also a similarity) matrix.
- With \(p\) large-ish \(\Sigma^{-1}\) might be hard to estimate might just substitute
\[ G_d = X \textrm{diag(diag}(S_p))^{-1}X^T \]
or even
\[ G_u = XX^T \]
Different featurization
- Suppose we featurize \(X\) differently, i.e. instead of rows \(X[i,]\) we consider \(h:\mathbb{R}^p \rightarrow\mathbb{R}^k\) a new data matrix
\[ \mathbb{R}^{n \times k} \ni h(X) = \begin{pmatrix} h(X_1) \\ h(X_2) \end{pmatrix} \]
with
\[ h(X_i) = \begin{pmatrix} h(X_i[1]) \\ \vdots \\ h(X_i[n_i]) \end{pmatrix} \]
- Can just as easily “compute” Hotelling \(T^2\) with \(h(X)\) instead of \(X\)
\[ \textrm{Tr}(G^hP^{\Delta}) \]
with
\[ G^h_{ij} = h(X[i]) (S_p^h)^{-1} h(X[j]) \]
with \(S_p^h\) a pooled estimate of covariance from \(h(X)\). Or, might use diagonals only…
Calibration by permutaion
Under \(H_0: F_1=F_2\) a simple permutation procedure can be used.
First, let’s assume that for some fixed \(h\) (recall that \(X\) is the full data matrix).
\[ G_{ij}=G_h(X_1,X_2)_{ij} \overset{def}{=} K(X_i, X_j) \]
- Compute our observed test-statistic
\[ W_{obs} = \textrm{Tr}(GP^{\Delta}) \]
Permutation distribution
- For \(B\) independently drawn random permutation \(\sigma\) (viewed as a 0-1 matrix), define
\[ \begin{aligned} P^{\Delta}(\sigma) &= \sigma P^{\Delta} \sigma^T \\ W(\sigma) &= \textrm{Tr}(P^{\Delta}(\sigma)GP^{\Delta}(\sigma)) \end{aligned} \]
- Report \(p\)-value
\[ \frac{1}{B} \sum_{b=1}^B 1_{[W_{obs},\infty)}(W(\sigma)) \]
- Some parameters in the Gram matrix \(G\) might depend on \(X\) – under some conditions plugin principle might work, else could recompute \(G\) for each \(\sigma\).
Example
Let’s add quadratic in
oleicas well if we suspect 2nd moment ofoleicis also different…Moral: the idea from regression of adding extra features can also be used for testing…
Z_1H = cbind(X_1H, qoleic=X_1H[,'oleic']^2)
Z_2H = cbind(X_2H, qoleic=X_2H[,'oleic']^2)
T = hotelling.test(Z_1H, Z_2H, perm=TRUE, progBar=FALSE)
print(T)
Test stat: 0.3571
Numerator df: 9
Denominator df: 313
Permutation P-value: 0.9526
Number of permutations : 10000