David Kewei Lin
Welcome to my personal site!
A better gap bound
$\providecommand\opnorm[1]{\|#1\|_\mathrm{op}}$
$\providecommand\eps\varepsilon\providecommand\E{\mathbb E} \providecommand\GAP{\mathsf{GAP}} \providecommand\tr{\mathop{\mathrm{tr}}} \providecommand{\diag}{\mathop{\mathrm{diag}}} \providecommand\norm[1]{\left\|#1\right\|} \providecommand{\Var}{\mathrm{Var}} \providecommand\lrangle[1]{\langle#1\rangle}$
In a previous blogpost I proved a mean-field gap bound for PSD matrices in the high temperature regime that has the correct dependence on the temperature $O(\beta^2)$. I recently revisited this problem and found a much better tool to use that allows us to not only do this for all symmetric matrices $J$ but also deal with an external field $h$.
Statement
Let $\beta\ge0$, let $J\in\mathbb R^{N\times N}$ be symmetric, and let $h\in\mathbb R^N$. For the partition function
$$Z = \sum_{\sigma\in \{-1,1\}^N} \exp\left(\frac \beta 2 \sigma^\top J \sigma + \lrangle{h,\sigma}\right),$$
we have the following gap bound:
$$\GAP \le C\beta^2 \|J^\circ\|_F^2 \qquad \text{when }\beta\opnorm{J^\circ}\le C',$$
where $C,C'>0$ are absolute constants and $J^\circ$ is the off-diagonal part of $J$.
Using $J^\circ$ in the conclusion is really the same as saying “WLOG, assume the diagonal of $J$ is zero”. Since $\sigma_i^2=1$, the diagonal contributes the constant $\frac\beta2\tr J$ to both the exact and mean-field free energies. So henceforth we will assume $J$ has zero diagonal. The key consequence is that for any product measure $\nu$, independence gives $\E_\nu \sigma^\top J \sigma = m^\top J m$, where $m := \E_\nu \sigma$.
Recall the mean-field approximation, where we optimize over product measures:
$$ \GAP = \log Z - \sup_{\nu\text{ product}} \left\{\E_\nu f + H(\nu)\right\}, $$
with $f(\sigma)=\frac\beta2\sigma^\top J\sigma+\lrangle{h,\sigma}$ and $H(\nu)=-\E_\nu\log\nu$.
Now suppose that we plug in the product measure $\nu(\sigma)=e^{\lrangle{h,\sigma}}/Z_\nu$, where $Z_\nu=\prod_i2\cosh h_i$. Its entropy is exactly $H(\nu)=\log Z_\nu-\E_\nu\lrangle{h,\sigma}$, so
$$ \begin{align*} \GAP &\le \log Z - \E_\nu \left[\frac \beta 2 \sigma^\top J \sigma + \lrangle{h,\sigma}\right] - \left(\log Z_\nu - \E_\nu [\lrangle{h,\sigma}]\right) \\ &= \log \E_\nu \exp\left(\frac \beta 2 \sigma^\top J \sigma - \E_\nu\left[ \frac \beta 2 \sigma^\top J \sigma\right]\right) \end{align*} $$
We would like the log-MGF on the right to be $O(\beta^2\|J\|_F^2)$ for small $\beta$. I have actually blogged about the connection between MGF bounds and subgaussianity before here. Turns out, there’s a theorem that controls quadratic forms in independent centered subgaussian variables! We will need to revisit our choice of product measure to handle the fact that $\sigma$ is not centered.
Subgaussianity
First, a quick note on subgaussianity. A centered random variable $X$ is said to be subgaussian if, for some $K>0$, its tails satisfy
$$P(|X| \ge t)\le 2\exp\left(-\frac{t^2}{2K^2}\right)\qquad(t\ge0).$$
The Gaussian $K\gamma$, where $\gamma\sim\mathcal N(0,1)$, satisfies this tail bound too. There are a bunch of equivalent formulations, including:
- $\E[\exp(tX)] \le \exp(K_1^2 t^2/2)$ for every $t\in\mathbb R$;
- $\E[\exp(X^2/K_2^2)] \le 2$.
The parameters $K_1,K_2$ can be chosen within an absolute constant factor of $K$, and conversely. The quantity $K_1^2$ in the MGF bound is called a variance proxy. (There are actually a bunch of these definitions.)
So what I failed to realize when I was looking at a theorem like this:
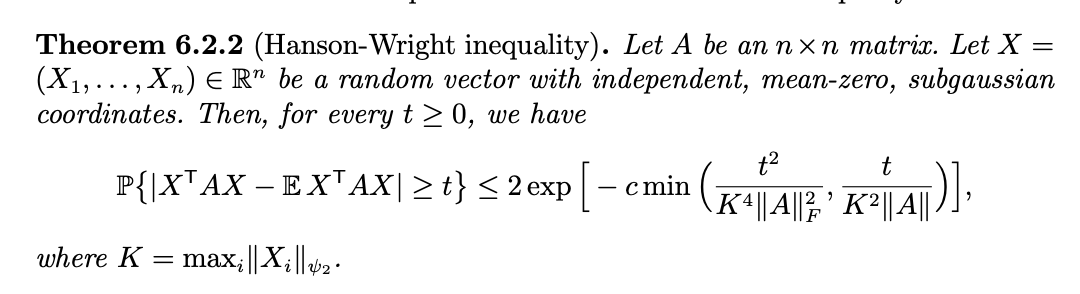
… I was also looking at a bound on the MGF, which is something that is much more useful for me. Notice that the tail exponent has both a quadratic and a linear regime: the corresponding MGF bound has Gaussian form only for sufficiently small parameters. That is exactly the range we need at high temperature.
In particular, the first criterion means that we can switch a centered $X$ out for $K_1\gamma$ inside this exponential expectation, where $\gamma$ is an independent standard normal:
$$\E[e^{tX}] \le \E[e^{tK_1\gamma}].$$
The coefficient $t$ could even be a random variable independent of $X$: condition on $t$ and take $\gamma$ independent of both. More generally, the same argument works whenever the conditional MGF satisfies the same bound.
Chaos
Chaos is the term used here for a quadratic form with zero diagonal in independent centered variables. For independent symmetric $\{-1,1\}$ variables, this is a Rademacher chaos. I outline the approach from Rudelson-Vershynin to bound the MGF for small parameters: the two ideas are (1) a known trick from HDP Ch 6.1 and (2) switching out things for independent Gaussians. The first trick is the decoupling for chaoses:
(Decoupling argument) Let $X = (X_1, \ldots, X_n)$ be a mean-zero random vector with independent coordinates, and suppose $A_{ii}=0$. Then
$$\E \exp(X^\top A X) \le \E \exp(4X^\top A X')$$
where $X'$ is an independent copy of $X$.
The ingenious step is to pick a random subset $S\subset[n]$ uniformly from all subsets. Each pair of distinct indices satisfies $i\in S$, $j\notin S$ with probability $1/4$, so
$$ X^\top A X = \sum_{i\ne j} A_{ij} X_i X_j = \E_S \left[4\sum_{i\in S, j\notin S} A_{ij} X_i X_j\right]. $$
Jensen’s inequality lets us move the expectation over $S$ outside the exponential. For fixed $S$, the two groups of coordinates are independent, so we can then replace the coordinates in $S^c$ by their copies in $X'$:
$$ \begin{aligned} \E_X \exp(X^\top A X) &\le \E_{S,X}\exp\left(4\sum_{i\in S,j\notin S}A_{ij}X_iX_j\right)\\ &=\E_{S,X,X'}\exp\left(4\sum_{i\in S,j\notin S}A_{ij}X_iX_j'\right). \end{aligned} $$
To finish, fix $S$ and write
$$Y=\sum_{i\in S,j\notin S}A_{ij}X_iX_j',\qquad Z=X^\top A X'-Y.$$
Now, notice that $Z$ conditioned on $\{X_i\}_{i\in S}$ and $\{X_j'\}_{j\in S^c}$ has mean zero, so $Z$ conditioned on $Y$ has mean zero. Conditional Jensen gives $\E\exp(4Y)\le\E\exp(4(Y+Z))=\E\exp(4X^\top A X')$. Averaging over $S$ proves the lemma.
The implication here is that if the $X_i$ are centered subgaussian variables with variance proxy $K^2$, then one can comfortably bound the RHS. Recall from earlier that this means $\E\exp(tX_i)\le\exp(t^2K^2/2)$ for every real $t$. Let $\gamma,\gamma'$ be independent standard Gaussian vectors, independent of $X,X'$. Applying the comparison one coordinate at a time in each vector gives
$$ \begin{align*} \E \exp(tX^\top A X') &\le \E \exp\left(tK X^\top A \gamma'\right) \\ &\le \E \exp\left(tK^2 \gamma^\top A \gamma'\right)\\ &= \E \exp\left(t^2K^4 \|A \gamma'\|_2^2/2\right)\\ &= \det(I - t^2K^4 A^\top A)^{-1/2}, \end{align*} $$ where we require $|t|K^2\opnorm A<1$. Combining this with decoupling, including its factor of $4$, gives the following bound whenever $4|t|K^2\opnorm A<1$:
$$ \log\E\exp(tX^\top A X) \le-\frac12\log\det(I-16t^2K^4A^\top A). $$
For example, when $|t|K^2\opnorm A\le1/8$, the inequality $-\log(1-u)\le2u$ for $0\le u\le1/2$ bounds this by
$$ \log\E\exp(tX^\top A X)\le16t^2K^4\tr(A^\top A)=16t^2K^4\|A\|_F^2. $$
This is exactly the kind of bound that we want. We still need to choose the product measure so that the exponent involves a quadratic form in centered spins.
Dealing with centering
There is one hiccup: $\sigma$ isn’t centered under our first choice of $\nu$. It will help if we expand the expression in more generality. Let $\nu=\nu_m$ be the product measure with means $m\in(-1,1)^N$, so $\nu_m(\sigma)=e^{\lrangle{\tilde m,\sigma}}/Z_\nu$ with $\tilde m:=\tanh^{-1}m$ elementwise. Then
$$ \begin{align*} \GAP &= \log Z - \E_\nu \left[\frac \beta 2 \sigma^\top J \sigma + \lrangle{h,\sigma}\right] - \left(\log Z_\nu - \E_\nu [\lrangle{\tilde m,\sigma}]\right) \\ &= \log \E_\nu \exp\left(\frac \beta 2 (\sigma^\top J \sigma - m^\top J m) + \lrangle{h-\tilde m, \sigma - m} \right) \\ &= \log \E_\nu \exp\left(\frac \beta 2 (\sigma - m)^\top J (\sigma - m) + \lrangle{\beta J m + h-\tilde m, \sigma - m} \right) \end{align*} $$ The linear coefficient $\beta Jm+h-\tilde m$ is precisely the gradient of the mean-field free energy:
$$\mathcal F_{MF} (m) := \frac \beta 2 m^\top J m + \lrangle{h, m} + H(\nu_m).$$
Indeed, $\nabla_mH(\nu_m)=-\tanh^{-1}m$. Choose a maximizer $m^\star$ of $\mathcal F_{MF}$ over $[-1,1]^N$. For finite fields, the entropy’s infinite slope at the boundary makes the maximizer interior, so
$$\beta Jm^\star+h-\tanh^{-1}m^\star=0.$$
At this choice the first inequality is an equality and the linear term vanishes. Writing $X=\sigma-m^\star$ under $\nu_{m^\star}$, we get
$$\GAP=\log\E_{\nu_{m^\star}}\exp\left(\frac\beta2X^\top JX\right).$$
The $X_i$ are independent, centered, and supported on intervals of length $2$. Hoeffding’s lemma gives $\E e^{tX_i}\le e^{t^2/2}$, so we can use the preceding MGF bound with $K=1$, $A=J$, and $t=\beta/2$. This proves
$$\GAP\le4\beta^2\|J\|_F^2\qquad\text{when }\beta\opnorm J\le\frac14.$$
Restoring $J^\circ$ proves the stated result, for example with $C=4$ and $C'=1/4$, uniformly over the external field $h$.
Expansion about the mean
There’s a good explanation for the little miracle in the algebraic manipulation from the last section. We’ll do the same thing but this time not unpack $f$:
$$ \begin{align*} \GAP &= \log Z - \E_\nu f - H(\nu)\\ &= \log \E_\nu \exp\left(f(\sigma) - \log \nu (\sigma) -\E_\nu f - H(\nu)\right) \end{align*} $$
If we think of $\nu$ as centered around $m$, then we can try to interpret this as a Taylor expansion about $m$. The nice thing is that because of the hypercube structure, $f(\sigma)$ and $-\log \nu (\sigma)$ are quadratic and linear functions of $\sigma$, so one just needs to compute the gradient: $$ \begin{align*} f(\sigma) &= f(m) + \nabla_m f(m)^\top (\sigma - m) + \frac{\beta}{2} (\sigma - m)^\top J (\sigma - m)\\ -\log \nu (\sigma) &= H(\nu) + \nabla_m H(\nu)^\top (\sigma - m) \end{align*} $$
Therefore, $\mathcal F_{MF} = f + H(\nu)$ appears as both the zero-th and first-order terms in this expansion, so by minimizing it we get rid of the linear term.
What’s left?
For $h=0$, this basically gives a gap bound which is within a constant factor of optimal (and in particular, has the right dependence on $\beta$). We know this because of the quenched spin-glass construction. However, with nonzero $h$ the correct answer is actually
$$\frac{\beta^2} 4 \sum_{i Unfortunately, there is no chance that we obtain this bound with the same technique - in the Hoeffding step we lose the “tightness” of the second derivative that is required. I think we start to stand a chance if we can understand how to perform the decoupling in a more general (and maybe optimal) way.